UX Designer

UX designer who checks the claims.

I'm Raphaella, a UX designer who builds amazing things.

Selected projects

Postcards from my work.

wish you were here!

American Steel Carports preview
N° 01/03 · 2025–2026

American Steel Carports

A homepage fix that became a full site redesign.

31 state pages, a design system and 49 mobile frames. Live site audited at WCAG 2.1 AA “C-”. Headed to dev handoff; no post-launch metric yet.

01Case study
FromRaphaella, Dallas TX
ToWhoever is reading
  • Website redesign
  • Sole UX designer
BonGusto preview
N° 02/03 · 2024

BonGusto

Two personas, one recipe app, and a gap found in hindsight.

13 of 15 survey respondents preferred rounded recipe cards, so they shipped. Phase 1 prototype from a school project; no product shipped.

02Case study
FromRaphaella, Dallas TX
ToWhoever is reading
  • Research · IA
  • Paper tested
CLV Predictor preview
N° 03/03 · 2026

CLV Predictor

Not a design project. I’m moving toward work that sits between design and code, and this is the first piece of it.

A paid course contradicted its own lesson.

Real R² of 0.069, not the template’s 78% accuracy. Four models trained, tested FastAPI endpoint, public on GitHub. A learning project, not a shipped product.

03Case study
FromRaphaella, Dallas TX
ToWhoever is reading
  • Machine learning
  • Solo learner
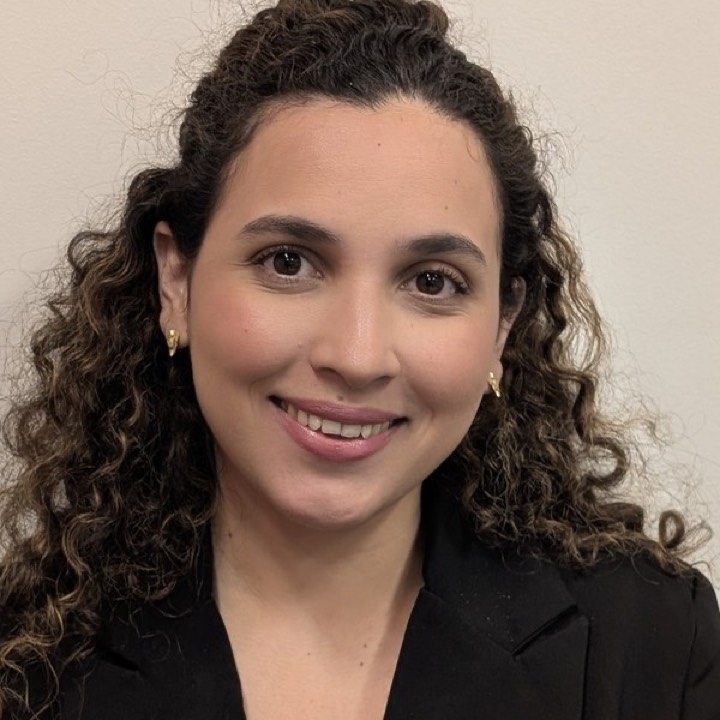
Raphaella Stillwell, smiling, in a black blazer
hi, it's me!

About me

Hello, I’m Raphaella.

I’m a sole UX designer at American Steel Carports. Before design I spent years in customer support, business support and media operations, where a wrong number had an immediate cost. That’s where the habit came from: research first, verify before designing, keep the judgment calls with a person.

I’m based in Dallas, TX, and that customer-support background shaped my understanding of, and empathy for, user needs. I’m passionate about user research, interaction design, and creating intuitive experiences that make a real impact.

  • Open to enterprise product roles
  • Dallas, Texas
  • English and Spanish
research first, always →

Résumé

The paper trail.

Download the PDF ↓

Raphaella StillwellUX Designer

Work experience

UX Designer · American Steel CarportsJoshua, TX · Aug 2025 – Present

Lead end-to-end UX strategy as the sole designer, driving research, IA, and design execution while aligning stakeholders and engineering to deliver a full website redesign.

Before design: customer support, business support, and media operations — where the research-first habit came from.

Postcard · American Steel Carports

Postcard
from

American Steel

Website redesign · 31 state pages · design system · 49 mobile frames

From
Raphaella, Dallas TX
To
Whoever is reading this
Re
American Steel Carports · Sole UX designer · 2025 – 2026

A homepage fix that became a full site redesign, once the research made the case for it.

The redesigned American Steel Carports homepage: a clear headline, product entry points, and a photo of a red steel garage
The redesigned homepage.
Role
Sole UX designer, end to end
Timeline
2025 – 2026 · in dev handoff
Problem
Brief said “fix SEO and homepage conversion.” Research said the site was a catalog with no path for an undecided buyer, a quote form that lost leads, and product claims that didn’t match the product.
What I did
Research, IA, design system, 31 state pages, 49 mobile frames, dev handoff. Fact-checked every claim against the client’s experts.
Result
A fact-corrected, fully responsive site in dev handoff. The version in handoff hasn’t been user-tested yet; the eight sessions on the first redesign are the user evidence behind it.
Methods
WCAG 2.1 AA audit · competitive benchmark · moderated usability testing (8, on the first redesign) · stakeholder fact-check rounds
Tools
Figma · HTML prototypes · scripted page generation

What the brief said, and what the research said

American Steel Carports hired me as sole UX designer to fix SEO structure and homepage conversion, per two stakeholder Loom videos. Two pieces of research on the live site made the case for something much bigger.

The WCAG 2.1 AA audit came back at an overall C-. The costliest issue: the quote request form, the core revenue path, had no associated field labels, no error handling, and no required-field indicators.

The live American Steel Carports quote form on a dark grey page, starting at the line “All Fields Are Required *”. Fields are Your Name, What Service Are You Looking For, Email Address, Zip Code, Phone Number and Describe Your Request. The field names appear only as placeholder text inside the white boxes; Zip Code has no asterisk and the others do. Below the fields is an unchecked box with the sales-department text-message consent. No field shows an error.
The live quote form: placeholder-only labels, no required mark on every field, no error state.
The redesigned quote form, step 1 of 3 (Contact Info, then Building Details, then Confirm): a progress bar with step 1 in progress, the heading “Step 1: Tell Us Who You Are”, labelled fields with red required asterisks for First Name, Last Name, Phone Number, Email Address and ZIP Code, a red “Next: Building Details” button, and the note “Your information is never shared or sold. View our Privacy Policy.”
The redesigned form: labels, required marks, one step at a time.

ASC had no funnel analytics, but its quote-tracking system showed a meaningful share of requests stalling after the first step; the broken form explains the drop. Also found: color contrast failures (the roughly 8% of men with color-vision deficiency), keyboard navigation unusable without a mouse, missing alt text, and no semantic headings or skip links.

The benchmark of seven direct competitors showed why it mattered: ASC read as functional but outdated, with an underused 3D configuration tool and none of the animation, microinteraction, or modern trust-building patterns that direct competitors were already using.

What users told us

The first redesigned version tested “okay.” Okay wasn’t good enough, and I had eight people telling me why.

Eight moderated usability sessions, with eight participants matching ASC’s buyer profile: rural property owners and small-business buyers researching a carport or garage. The pattern across sessions was consistent: participants could find a product but couldn’t tell whether ASC served their state and wanted the licensed-states list on the homepage, couldn’t tell what a quote would cost them, and assumed the single product photo was the exact building they’d receive.

Two concrete changes came straight out of this. The generic trust slider was replaced with a static trust row and a states-list panel showing where ASC is actually licensed. And every product moved to a multi-image gallery with a made-to-order line underneath, because the single hero photo had made testers think that exact building was what they’d get.

The site behaved like a catalog, not a guide.
How I put the case to stakeholders

Making the case

Both pieces of research pointed at the same problem: the site only worked if a visitor already knew what they wanted. There was no path for someone still deciding, no upfront trust-building, no proof before price. Fixing that meant restructuring around “here’s how we help you” instead of “here’s what we sell.” The stakeholders agreed, and I owned the redesign end to end.

Before and after

The live homepage led with a coverage map and a slogan. The redesign leads with what the buyer is trying to do.

The live American Steel Carports homepage: a coast-to-coast coverage map with a slogan over it
BeforeA catalog. A map, a slogan, and a Build Your Own button.
The redesigned homepage: a clear headline, product entry points, and a photo of a red steel garage
AfterA guide. Headline, product paths, proof before price.
The full redesigned homepage, top to bottom: products, process, trust, reviews, contact
The full pageTap the image to enlarge.
  1. Product paths Hero chips: pick what you’re building.
  2. Proof before price Trust row and states panel.
  3. Made to order Gallery microcopy under each product.
  4. Financing up front Financing strip.

Then the facts

Verifying the site’s existing claims against real product specs became part of the work. The site serves 31 legally and materially distinct states, so licensing, snow loads, seismic zones, and permit requirements are all state-specific, and almost nothing could be fixed sitewide. Ground truth arrived in batches across four client expert review rounds, so it kept shifting under the work.

Some of what those rounds turned up:

The site claimedThe product expert saidWhat changed
Wind-rated 130–150+ MPHEvery building is rated to 100 MPHFixed across product cards, trust sections, and 25 state-page stats
Licensed in 31 statesServes 31; holds a direct license in 21, plus 4 through partner ACILicensing panel rewritten to list only the 25 licensed states; “serving 31 states” kept as a separate claim
Fire-ratedNothing is fire-ratedAll 15 fire mentions removed
Snow, ice, hail, hurricane-readyStandard snow load is 30 lbs; higher ratings are purchasable upgradesReworded as upgrades, with cost language
PE-stamped drawings includedFree generic plans; site-specific stamped plans are purchasedPermit answers rewritten on 7 state pages
Installs on sloped sitesBuildings require a level siteClaims reversed on WV and VA

Where ambiguity was real, such as FAQ answers citing county wind codes, I flagged it for the client rather than rewriting. Where a claim was simply false, it came out.

The redesigned licensing panel, titled “States we’re licensed in”: Arizona, Utah, Colorado, New Mexico, Texas, Oklahoma, Arkansas, Louisiana, Missouri, Iowa, Minnesota, Wisconsin, Illinois, Tennessee, Kentucky, Indiana, Michigan, Ohio, West Virginia, Pennsylvania, and New Jersey. Below it: Washington, Oregon, California and Nevada are served through the installation partner, ACI.
The licensing panel, rewritten: the 25 states with a license, listed by name.
C-Overall WCAG 2.1 AA rating of the live site before the redesign.

Accessibility auditThe research that justified the full redesign.

StalledQuote requests sitting in the client’s tracking system with no next step. Traced to a form with no labels, no error handling, no required-field marks.

Core revenue pathThe costliest finding.

7 competitorsHeuristic review of seven direct competitors in the metal-building market for trust patterns, configurators, and motion — feature presence, not performance data.

Competitive benchmark

150 → 100 MPHEvery building is rated to 100. The site claimed 130–150+ in cards, trust sections, and 25 state stats.

Corrected claimThe less impressive number is the true one.

31 → 21States the site said ASC was licensed in, versus states it is. It serves 31; the panel now lists only the 25 with a license.

Corrected claimThe one that changed the homepage.

The design system underneath

None of the redesign could be built reliably on the file I inherited, so the system came first. Four typefaces were consolidated into one unified type system, thirteen stale text styles were retired, and the broken component variants were rebuilt so that every page draws from the same parts. That foundation is what let 31 state pages and 49 responsive mobile frames stay consistent while the facts underneath them kept changing, and it's what the dev team is picking up at handoff. The states-list panel that replaced the generic trust slider is one of those components: a single, reusable block that shows the real licensed states wherever it's needed.

4 → 1Typefaces in the inherited file, consolidated into one unified type system.

TypographyOne voice across every page.

13 retiredStale text styles cleaned out before anything new was built.

Text stylesOnly the styles the site actually uses.

RebuiltBroken component variants fixed, so 31 state pages and 49 mobile frames share the same parts.

ComponentsConsistent at scale, ready for handoff.

All 31 state pages in a grid of four rows: each page has the same layout, with a headline reading “Metal Carports & Steel Buildings in” a state, a row of stats, a “Why [state] chooses steel” section and a product photo.
All 31 state pages, built from one template.

How the 31 pages got built

One designer can’t hand-build 31 state pages and 49 mobile frames on this timeline, and I didn’t try to. I designed the page template and the components in Figma, wrote the rules for how each state page should vary (hero, stats, service-area groups, FAQ), and used AI-assisted generation to produce the pages from that template. Every generated page went through me. I reviewed each one, corrected facts carried over from the wrong state, layout drift, and FAQ answers that overclaimed, and sent back anything that didn’t match the system. For example, the generator carried a Texas CTA onto the Pennsylvania page, and nine Texas city cards showed up on Colorado. The decisions (what to build, what the template allowed, which claims stayed) were mine. The tooling did the typing.

Three decisions that cost something

Decision 1

Redo the entire site after the first version tested “okay.”

Problem
The first redesign tested “okay.” Eight participants couldn’t tell whether ASC served their state or what a quote would cost, and assumed the single product photo was the exact building they’d receive.
Alternative
Adjust the first version.
Why
The sessions said the information needed reorganizing and supplementing, not adjusting. The states-list panel that replaced a generic trust slider was one instance of that larger call.
How I checked it
Eight moderated sessions on the first redesign. The version in handoff hasn’t been user-tested yet.

Decision 2

Tell the homepage the truth about licensing.

Problem
The site said licensed in 31. The client’s experts said 21 directly, 4 through partner ACI. ASC serves 31.
Alternative
List all 31 and footnote the licensing.
Why
The panel was rewritten to list only those 25, with “serving 31 states” as its own line. The smaller number is less impressive, and it’s the accurate one.
How I checked it
Against the client’s product experts, across four expert review rounds.

Decision 3

Correct wind ratings sitewide.

Problem
The site claimed 130–150+ MPH. The product expert said every building is rated to 100.
Alternative
Where ambiguity was real, such as FAQ answers citing county wind codes, flag it for the client instead of rewriting it.
Why
Where a claim was simply false, it came out. Where it was ambiguous, it was the client’s call.
How I checked it
Fixed across product cards, trust sections, and 25 state-page stats, against the client’s product expert.

Outcome

A fact-corrected, typographically unified, fully responsive site across 31 state pages and 49 mobile frames, with a design system the dev team can build on. It’s in dev handoff with go-live expected late 2026, so there is no post-launch metric yet. The version in handoff hasn’t been user-tested; the eight sessions on the first redesign are what drove it. Next step: test the shipped version with users.

Reflection

Fact-checking should have been in the scope from day one. It wasn’t, and it became the biggest part of the work only once actual checking started. Next time I’d budget for it up front: a claims inventory before design, and a client expert in the review loop from the first round, not the fourth. The other lesson is about evidence when there isn’t much. ASC had no funnel analytics, so the research came from the one system they did have, a WCAG audit, and eight people in a room with the first redesign. That was enough to know what to fix and what to throw out.
with care,Raphaella's monogram

Postcard · BonGusto

Postcard
from

BonGusto

Recipe discovery app · research · IA · interaction design · prototyping

From
Raphaella, Dallas TX
To
Whoever is reading this
Re
BonGusto · Sole designer, school project · 2024

Two personas, one recipe app, and a gap the research had already shown me.

Two phone screens side by side. Left, Home: a search bar, a popular recipe photo, a row of chef profile photos under “The chefs you might like”, and a popular tag with recipe cards; its caption reads “Gabriela’s screen: discovery, chefs to follow, a trending tag.” Right, Collections: a search bar, an “Add new collection” tile and collection tiles such as All Favourites, Ideas for dinner and Ideas for brunch; its caption reads “Pete’s screen. The only one.”
Gabriela’s screen, and Pete’s.
Role
Sole designer, end to end
Timeline
2024 · school project
Problem
An open brief: design a recipe discovery app and decide who it’s for. I chose two users with different jobs and had to make one app serve both.
What I did
Two personas with journey maps, a 15-person user survey, paper-prototype testing, IA, MoSCoW prioritization, wireframes, visual design, a Phase 1 Figma prototype.
Result
A tested Phase 1 prototype. The survey supported the achievements system I built for one persona, and also contained the evidence for the other persona’s features, which I ranked lower and never built. Not shipped; no product metrics.
Methods
User survey (15) · paper-prototype testing · three-way design-option tests · preference tests
Tools
Figma · paper prototypes · Google Forms

A choice the brief didn’t require

The assignment was open: design a recipe discovery app and choose who it’s for. I chose two users instead of one.

Gourmet Gabriela wants to build cooking skill and explore techniques. Party Pete plans multi-dish meals for guests and needs to coordinate the work of hosting. I mapped both journeys. Pete’s ran from planning a menu through prep and hosting, and the opportunities row listed what he’d need: a crowd-pleaser filter, a menu planner, one-click serving adjustment, a prep timeline.

Two personas sounds like more coverage. In practice it’s harder: each has to feel like the app was built for them, without the whole thing reading as two apps stitched together.

Opportunities row from Party Pete’s journey map: crowd-pleaser filter, drag-and-drop menu planner, one-click serving adjustment, ingredient availability checker, party-preparation timeline, adaptive checklist, plating and pairing tips.
Pete’s journey map, opportunities row. The list of what I didn’t build.

What 15 people told me

Before high-fidelity design I ran a 15-person survey: cooking habits and challenges, interest in specific features, three-way comparisons of design options, and visual preferences. It was built to tell me what to prioritize. It did, and that’s where the problem started.

The strongest signal was for an achievements feature: fourteen of fifteen were very or somewhat interested, and eleven wanted achievements based on trying new cuisines. That’s Gabriela’s job, and I built it.

Pete’s job was in the same survey. Seven of fifteen named balancing prep time as a cooking challenge, tied for the top. Eleven said they’d use serving adjustment. Nine picked a shopping-list layout as easiest to use. Stated interest isn’t proof a feature is needed, but it was the same kind of evidence I’d used for achievements, and every one of those responses scored lower, so every one ranked lower when I prioritized.

14 of 15Interested in an achievements feature.

The strongest signal in the surveyI built it.

7 of 15Named balancing prep time as a cooking challenge, tied for the top.

Pete’s problemIt got a placeholder.

11 of 15Would use serving adjustment for smaller or larger groups.

Pete’s needBuilt as a stepper, not a planning flow.

13 of 15Preferred rounded recipe cards over square.

The one visual decision I can put a number onIt’s small.

Two donut charts from the 15-person survey: 14 of 15 interested in an achievements feature; 13 of 15 interested in serving adjustment.
Both personas, same survey. One got built.

The paper test

I also paper-tested the core flows with one participant before building in Figma, around three tasks: find a chef or recipe through search, like and comment on a recipe, and adjust servings. With one person it was an exploratory pass, not evidence the design worked. Navigation went smoothly. Commenting didn’t, and on review the cause was my task wording rather than the screen, so the script changed before the UI did. The participant singled out serving adjustment as useful for hosting, which I noted and did not act on.

The screens

Six Phase 1 screens in a row: Login, Home, Search, Result, Chef profile and Collections. Numbered markers sit on the chefs row of Home (1), on a recipe card in Chef profile (2) and on the Add new collection tile in Collections (4). A red note under Chef profile reads “3 = Achievements screen: not in the export”.
Phase 1. Five screens for Gabriela, one for Pete.
  1. Discovery Home: a popular recipe, chefs to follow, a trending tag. Gabriela.
  2. Chef profile Recipes with time, difficulty and calories up front. Gabriela.
  3. Achievements Badges for trying new cuisines. Fourteen of fifteen asked for this. Gabriela.
  4. Collections Favourites and themed collections. The one screen for Pete’s planning job.

Pete’s planning flow was never built past Collections; a placeholder stood in for it in Phase 1.

Two phone screens side by side showing the same chef profile and recipe list: on the left the recipe cards have square corners, on the right they have rounded corners. A red arrow points at the first card on each side.
Thirteen of fifteen preferred rounded. They shipped.

Three decisions that cost something

Decision 1

Take two personas when the brief asked for one.

Problem
The assignment was open. One persona is the safe read; two means every feature has to answer to both.
Alternative
Pick Gabriela alone. The app would have been coherent and the achievements system would have been the whole story.
Why
Hosting is a different job from learning to cook, and I wanted the harder problem.
How I checked it
I didn’t, properly. The survey mixed both audiences and I ranked by vote count. See Decision 3.

Decision 2

Build the achievements system first.

Problem
Limited time for Phase 1; one big feature, not two.
Alternative
Build Pete’s prep timeline or serving-adjustment flow first.
Why
Fourteen of fifteen survey respondents wanted achievements. It was the strongest signal I had.
How I checked it
The survey. The signal was real; the ranking was the mistake.

Decision 3

Build serving adjustment as a control, not as Pete’s planning flow.

Problem
Eleven of fifteen said they’d use serving adjustment. It could be a stepper on a recipe page or the first piece of a multi-dish planning flow for hosts.
Alternative
Build it inside a menu-planner where Pete scales several dishes at once.
Why
The stepper was faster to build and served everyone. The planner served one persona and needed screens that didn’t exist yet.
How I checked it
The paper-test participant said serving adjustment was useful for hosting. That was the signal it belonged in Pete’s flow, and I read it as a feature request instead.

The gap

A two-persona design can look balanced in the moment and not be. The research had already shown me where it wasn’t.
On the achievements system built for Gabriela, with no equivalent for Pete

I designed for two personas, but I didn’t carry both sets of needs through to the finished prototype.

When I revisited the project, the imbalance was clear. Gabriela had a home feed, chef profiles, and an Achievements system. Pete had a Collections screen, and his planning flow was a placeholder.

The survey had both audiences in it. Fourteen of fifteen were interested in achievements, and I built them. But seven of fifteen named prep time as a challenge, eleven wanted serving adjustment, and nine picked a shopping-list layout. Those were Pete’s needs, with the same kind of support. I prioritized the strongest overall signals rather than asking how the feature set served each persona.

That was the mistake: I treated the survey as a single ranking of features instead of considering whose needs each feature addressed. Looking back, I’d evaluate at two levels: how much a feature is worth overall, and how much it does for each persona’s core goal. The second question is what shows you when one audience is consistently getting less of the product.

Outcome

A tested Phase 1 prototype, built on a 15-person survey and a paper test. The survey supported the achievements system and I built it; it also supported Pete’s planning features and I didn’t. Not shipped; no product metrics. If I picked it up again, Pete would get a real planning flow first: a multi-dish timeline and a shopping list, both of which the survey already asked for.

Reflection

Two personas doubled the surface and I built the depth for one, even though the research for both was in the same form. The next time I take on more than one primary user, the check happens before I rank anything: for every feature, which persona’s goal does it serve, and what does the other one get. If one persona keeps coming up empty, the ranking is wrong, not the persona.

with care,Raphaella's monogram

Postcard · Customer Lifetime Value Predictor

Postcard
from

the CLV Predictor

Machine learning · audit · rebuild · public repository

From
Raphaella, Dallas TX
To
Whoever is reading this
Re
Customer Lifetime Value Predictor · Solo learner · 2026

A machine-learning audit, and the first step toward work that sits between design and code.

A paid course contradicted its own lesson. I rebuilt the project until it didn’t.

Scatter plot titled “Linear Regression: Predicted vs Actual CLV”. Predicted values stay in a narrow band across the whole range of actual values, while a dashed red line shows where perfect predictions would fall; high-value customers sit far below it.
Predicted vs. actual customer lifetime value. Predictions cluster into a narrow range despite wide variation in actual values, a visual sign of the weak fit (R² = 0.069).
Role
Solo learner. First ML project, no prior background.
Timeline
2026
Problem
The course’s documentation module shipped a sample README with results already filled in: 78% accuracy, a validated $110K ROI, four models compared. The notebook had trained two, and its real R² was 0.069.
What I did
Traced every claimed metric to a cell. Trained the two missing models. Found and fixed three bugs. Replaced the deployment stub with a tested FastAPI endpoint. Rewrote the report and README around what the notebook actually produced.
Result
A notebook that runs end to end without errors, four honestly evaluated models, a working endpoint, and a report that says the model doesn’t predict well and explains why. Public on GitHub.
Methods
Metric tracing · train/serve parity check · 5-fold cross-validation · holdout testing · residual analysis
Tools
Python · pandas · scikit-learn · FastAPI · GitHub

What the course said, and what the notebook said

I enrolled in a beginner course to build my first machine-learning project. One module taught me to evaluate models honestly: on this dataset the real R² was 0.069, and a model you can explain is worth more than a score you can’t. A later module presented a polished sample README whose numbers I couldn’t trace to the notebook: 78% accuracy, a validated $110K ROI improvement, results for four models when two had been coded. The closing checkpoint repeated them as if they were my result.

So I traced the template’s claims back to the notebook. The 78% accuracy and the $110K ROI had no evaluation results behind them. The four-model comparison included two models the course hadn’t coded. I rebuilt the evaluation, the deployment, and the documentation around what I could verify.

What 0.069 means

An R² of 0.069 means the model explains about 7% of the variation in customer lifetime value. In plain terms: with the features in this dataset, lifetime value is barely predictable. The notebook’s own diagnosis says why. Past spend and future spend have a correlation of 0.042 in this dataset: very little linear relationship between the two. That doesn’t prove every one of the 22 features is useless, but it goes a long way toward explaining the weak result. The sample is 504 customers against 22 features, which is thin. And the two time windows don’t match: features come from nine months of history, the target from the following fourteen. Whether matching those windows would recover any signal is an open question, and it’s the next thing to test.

R² 0.069What the notebook actually produced, Linear Regression, test set.

The real resultLess flattering, and true.

78% · $110KAccuracy and ROI the course’s sample README claimed, for models it never trained.

The templateTwo numbers with nothing behind them.

r = 0.042Correlation between a customer’s past spend and future spend in this dataset.

Most of the reason no model does well here

3 bugsTwo in the prediction path, one exposed by fixing the other; one in the evaluation.

Found by reading outputNot by asking a model.

Two bar charts comparing four models. Left, R² score: Linear Regression is highest, Random Forest and Neural Network are lower, and Gradient Boosting falls below zero. Right, mean absolute error: all four models are close together.
Four models, actually trained. The template had reported results for all four when two existed.

Then the facts

The template claimedThe notebook saidWhat changed
78% model accuracyR² = 0.069Report and README rebuilt around 0.069
Validated $110K ROI improvementNo ROI was ever measuredReplaced with three what-if scenarios, labeled illustrative
Random Forest winsLinear Regression 0.069, Random Forest 0.049; difference not significant (p = 0.082)Linear Regression selected, with the p-value stated
Four models comparedTwo codedGradient Boosting and a small neural net trained and reported
Deployment-ready predictorA stub; the demo zeroed nearly every predictionTwo bugs fixed, endpoint built and tested (details below)
Stable cross-validationA leakage pattern inflating the CV scoreCorrected; CV R² reported as 0.026 ± 0.128

What broke, and how I found it

Three issues I identified and corrected. Two were in the prediction path and one was in the evaluation, and they’re documented separately in the notebook.

1. Train/serve skew. The endpoint prepared a customer’s data differently from the way the model had been trained on it, so nearly every prediction came back as zero. I found it by building the endpoint and sending it a real request instead of assuming the stub worked.

2. A missing date filter, found inside the first fix. Once predictions stopped being zero, some customers showed negative “days since last purchase,” which is impossible. Inside the corrected code path, a missing date filter was letting transactions from after the analysis date into the features. A second filter closed it. It became visible only because the first bug was gone.

3. Cross-validation leakage. Separate from the other two. The cross-validation setup let information leak into the evaluation, so the results looked more reliable than they were. After correcting it, the cross-validated R² for Linear Regression was 0.026 ± 0.128; that’s the number in the README, not the flattering one.

The endpoint itself replaced a template stub that imported modules that didn’t exist. It wraps the notebook’s own scoring function and was tested in the notebook with three real requests: a health check, a prediction for an actual customer, and a deliberate miss to confirm the error handling.

Terminal-style output of three requests run inside the notebook with FastAPI’s TestClient: a health check returning status 200 and “healthy”; a prediction for customer C0045 returning status 200 with a predicted CLV, a segment, a recommendation and a maximum marketing budget; and a request for an unknown customer returning status 404 with a message that no transactions were found.
Health check, a real prediction, and a 404 on purpose. Run in the notebook, not assumed.

Three decisions that cost something

Decision 1

Rebuild the report around 0.069 instead of filling in the template.

Problem
The course handed me a finished-looking README. Filling in the blanks would have taken an hour and looked like a strong project.
Alternative
Use the template. It was the lesson’s own deliverable; nobody would have questioned it.
Why
The evaluation module two lessons earlier had taught me that the 78% was impossible. The README would have contradicted my own notebook.
How I checked it
Every metric in the final README traces to a specific cell. The ones that couldn’t be traced came out.

Decision 2

Report Linear Regression as the selected model, with the caveats attached.

Problem
Linear Regression had the highest R² (0.069); the neural net had the lowest error ($766 MAE vs $779). Neither gap is large at 504 customers.
Alternative
Report the neural net. It won on one metric and sounds more impressive.
Why
I chose on R² and interpretability, not because it won every metric, and I say so. It’s my selection under my criteria, not a proven winner. The only significance test I ran was Linear Regression against Random Forest (p = 0.082, no significant difference); the neural net wasn’t in it.
How I checked it
Holdout test for all four, 5-fold cross-validation for the top two. All four models’ numbers are in the README so a reader can disagree with the choice.

Decision 3

Replace the deployment stub with a tested endpoint.

Problem
The template’s deployment section imported modules that didn’t exist and called it production-ready.
Alternative
Leave the stub and the “deployment-ready” line. Most beginner projects do.
Why
An untested endpoint is a claim, not a feature. Building it is also how I found the train/serve skew: the first real request returned zeros.
How I checked it
FastAPI endpoint called with actual requests in the notebook; the second bug, negative days-since-last-purchase, showed up in that output.

Outcome

A notebook that runs end to end without errors, four honestly evaluated models, a tested API endpoint, and documentation that states the real output and explains why it’s weak. Public on GitHub, so every number can be traced to the cell that produced it.

What it isn’t: a shipped product, or evidence the predictor is ready for business decisions. Evaluating a model’s metrics and testing an endpoint establish that the code does what it says. Whether the predictions would help a business decide anything was never tested, and the report says so. The next step is the one the report names: check whether a matched feature and target window recovers any signal.

Reflection

Authority and correctness aren’t the same thing. The habit of checking holds regardless of which one you’d expect to be more reliable.

Asking why wasn’t a debugging tactic I reached for when something looked broken. It was how I approached a field I didn’t know, applied equally to code, metrics, and the course’s own text. It would have been easy to trust the “professional example” because it came later and looked more polished. What changed is the order I work in now: before I write a sentence that contains a number, I find the cell that produced it. If there isn’t one, the sentence doesn’t get written.

with care,Raphaella's monogram